Test integration failures after an app restart
A scoped integration restart recovery testing workflow with synthetic conditions, expected outcomes, evidence checks and practical next steps.
Direct answer
For integration restart recovery testing, use a reproducible fixture, explicit expected outcomes and evidence of the final business state. A single-process simulation cannot prove durable recovery; identify the storage and transaction boundary.
This is a scoped method for a founder or agency reviewing an existing app or integration. It defines test expectations; it does not describe an audit performed on a client system.
Define the fixture and policy
Stop a synthetic event worker after receiving an event and before recording its effect.
Use an authorized test environment and synthetic records. Record the release, identities, initial state and dependency conditions. Replace the example policy with your approved product policy before running the checks. If the required outcome is undecided, resolve that decision before classifying the implementation as defective.
Worked example and acceptance matrix
| Condition | Agreed expectation | Evidence to inspect |
|---|---|---|
| Restart before commit | Approved retry recovers safely | Durable event state |
| Restart after commit | Committed effect is not duplicated | Effect ledger |
| Memory loss | Recovery does not depend on process memory | Restart evidence |
All rows begin NOT RUN. The expectations belong to this example, not every product or provider. Preserve fail and blocked results rather than counting an unavailable dependency as a pass.
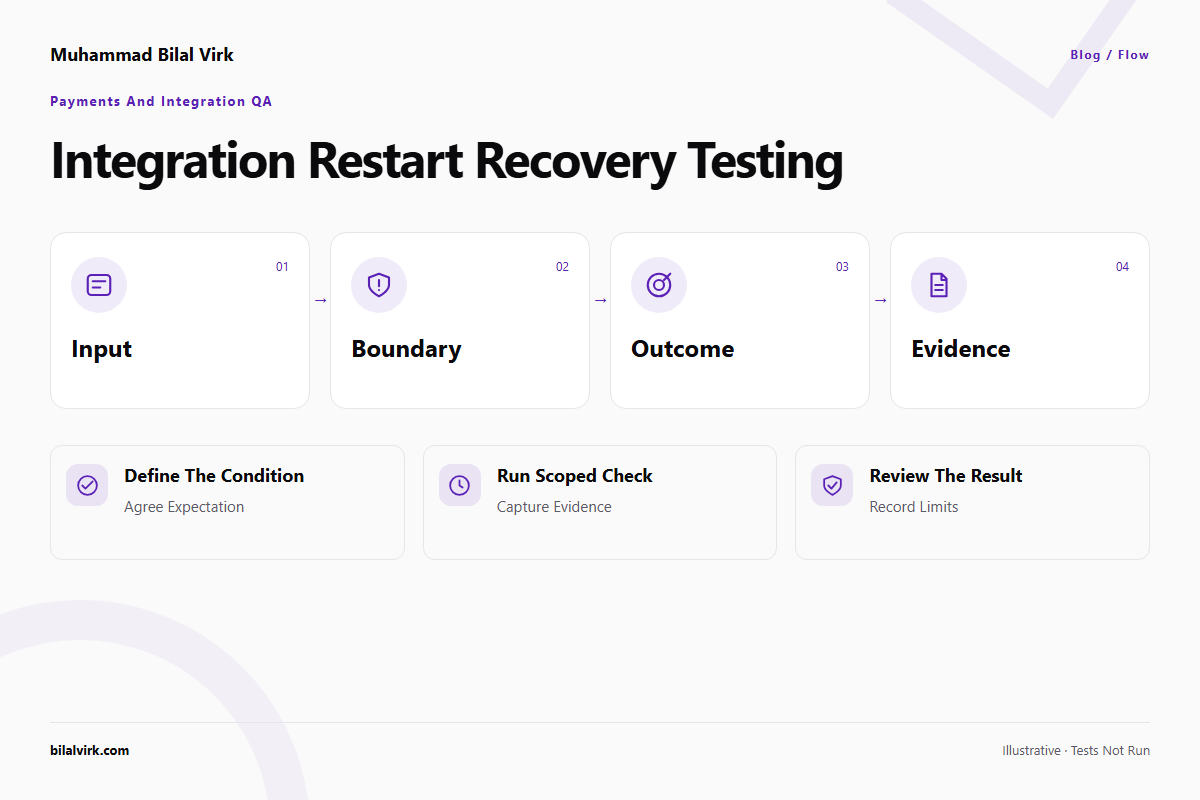
Run the conditions independently
1. Restart before commit
Set up this condition deliberately rather than waiting for it to occur during an ordinary click-through. For this fixture, the acceptance condition is approved retry recovers safely. Capture durable event state and compare it with the agreed initial state. A different result needs a reproduction record; missing access to that evidence makes the case blocked. Keep the condition separate from the other rows so one successful case cannot conceal a failure here.
2. Restart after commit
Set up this condition deliberately rather than waiting for it to occur during an ordinary click-through. For this fixture, the acceptance condition is committed effect is not duplicated. Capture effect ledger and compare it with the agreed initial state. A different result needs a reproduction record; missing access to that evidence makes the case blocked. Keep the condition separate from the other rows so one successful case cannot conceal a failure here.
3. Memory loss
Set up this condition deliberately rather than waiting for it to occur during an ordinary click-through. For this fixture, the acceptance condition is recovery does not depend on process memory. Capture restart evidence and compare it with the agreed initial state. A different result needs a reproduction record; missing access to that evidence makes the case blocked. Keep the condition separate from the other rows so one successful case cannot conceal a failure here.
Save a reproducible test record
The following original fixture can be copied into a test plan. Its identifiers are synthetic. It contains no production credentials and does not make network requests.
{
  "example": "synthetic; not executed",
  "scope": "Stop a synthetic event worker after receiving an event and before recording its effect.",
  "cases": [
    {
      "id": "day-52-case-1",
      "condition": "Restart before commit",
      "expected": "Approved retry recovers safely",
      "evidence": "Durable event state",
      "status": "NOT RUN"
    },
    {
      "id": "day-52-case-2",
      "condition": "Restart after commit",
      "expected": "Committed effect is not duplicated",
      "evidence": "Effect ledger",
      "status": "NOT RUN"
    },
    {
      "id": "day-52-case-3",
      "condition": "Memory loss",
      "expected": "Recovery does not depend on process memory",
      "evidence": "Restart evidence",
      "status": "NOT RUN"
    }
  ]
}
Add the actual result, a redacted evidence reference and the environment after execution. Reset state between cases that mutate records. When a response is uncertain, inspect the business receipt or persisted state before repeating the action.
Interpret the result and choose the next step
A single-process simulation cannot prove durable recovery; identify the storage and transaction boundary.
A failure report should name the affected condition, the observed difference and its business impact. A blocked result should name the missing dependency and its owner. After a repair, rerun the original failure and a relevant ordinary path against the new release. Keep untested conditions visible. This matrix does not establish exhaustive security, compliance, performance or integration coverage.
Use the paired tool
Webhook Replay Checklist provides a practical companion. Its dated enhancement is persisted versus in-memory recovery checklist. The planning worksheet creates named cases and exports your recorded outcomes; it does not automatically exercise your app. Use the tool's existing calculation or validation separately where relevant.
Related implementation context: Make.com Airtable Integration: How to Sync, Create, and Update Records Automatically; Retell AI Custom LLM Integration: How to Connect Your Own Model to a Voice Agent.
Implementation reference
Consult Stripe idempotent request reference for the underlying platform or method. The source is an implementation reference; the fixture and product expectations above are original illustrative conditions, not quoted provider guarantees. Confirm the documentation for your deployed version before implementation.
Frequently asked questions
What demonstrates restart before commit?
For this fixture, approved retry recovers safely. Inspect durable event state; a success message alone may not establish the approved outcome.
What if restart after commit cannot be reproduced?
Record it as blocked with the missing setup or dependency. Do not replace the missing evidence with the image or a generated expectation. The diagram is instructional, and this article reports no executed result.
When is a scoped review useful?
Request one when a critical condition fails, ownership is unclear or the team cannot determine what committed. Bring the reproduction and agreed policy.
Recommended action
Start with the matrix for integration restart recovery testing, then record evidence before accepting or repairing the result. Discuss a scoped repair and release review or book a discovery call. Share the stack and broken journey in the initial enquiry; arrange any required access separately.
Want this built against your real numbers?
A 30-minute call to scope the workflow, agent, or automation you actually need.